AI Poland - 19 November 2026

On-Premise AIwith Local Models

Application, documents and a local AI server connected within the same infrastructure

Rainer Hahnekamp

Multikino Złote Tarasy - Warsaw, Poland
1
Soverius AI - Rainer Hahnekamp, AI Engineer and Google Developer Expert. We build production-ready AI systems.
2 / 13
Soverius AI

Agenda

3
Soverius AI

Why local?

Why Local?

€

Cost Control

No provider charge per token.

Lock

Privacy

Keep code and context inside.

Disconnected plug

Independence

Reduce provider dependency.

4
Soverius AI

The Model Range

The Model Range Four category introductions use bars on expanding linear axes. The next step turns bars into dots on a logarithmic axis, then a compact overview reveals continuous use-case ranges. Total Parameters Linear Scale 0 1B 2B 4B 5B 6B 8B 10B 15B 20B 25B 30B 50B 100B 150B 200B 500B 1T 1.5T 2T 2.5T 3T 10T On-Device / Browser Desktop Workstation Data Center Microsoft Phi-4 Mini: 3.8B total parameters Microsoft Phi-4 Mini Gemini Nano: approximately 4B total parameters Gemini Nano Also: Gemma E2B / E4B
5
Soverius AI

01

User-Hosted

6
Soverius AI

Local RAG

🧑‍💻 USER QUESTION “The cooling room is too warm.What should I do?” MANUAL PASSAGE “Room temperature too high.” UNRELATED EXAMPLE “The printer is out of paper.” E5 Embedding model VECTORS [0.80, 0.60, 0.00] [0.76, 0.64, 0.12] [−0.50, 0.20, 0.84] Illustrative values · real embeddings: 768 dimensions COSINE SIMILARITY 0.99 Closer match −0.28 Different meaning QUESTION + SELECTED PASSAGE TEXT “The cooling room is too warm. What should I do?” Manual: check door seals; keep doors closed. [p. 6, 2.6] Gemma Language model ANSWER TO THE USER Check the door seals and keep doors closed. [p. 6, entry 2.6]
7
Soverius AI

Local RAG Demo

8
Soverius AI

AI In The Browser

Browser-Managed

Prompt API

Browser-selected model

  • Limited browser support
  • May be too small for the task
App-Managed

Transformers.js

General ML

  • Choose ONNX models
  • Text · Vision · Audio · Embeddings
  • WebGPU or WASM
App-Managed

WebLLM

LLM Inference

  • Choose MLC models
  • Chat · Text Generation
  • WebGPU
Model DownloadsBandwidth · Storage · Memory
9
Soverius AI

Prompt API Demo

10
11
Soverius AI

02

Self-Hosted

12
Soverius AI

The Local Stack

AGENT
  • Claude Code
  • Google ADK
  • Mastra
  • LangGraph
calls
INFERENCE ENGINE
  • llama.cpp
  • vLLM
runs
MODEL
  • Gemma
  • Qwen
  • Muse Glimmer
13
Soverius AI

AG-UI With A Local Model

1 / 7

Register the frontend tool

Milestone 05: a frontend tool call The browser registers set_view. Its definition reaches the model through CopilotKit and Google ADK. A user asks to change the view; the model selects the tool, and CopilotKit executes its browser handler. The browser changes the view and returns a result. The database and facility API remain part of the application. BROWSER Frontend app Angular Application UI View: snapshot CopilotKit User chat FACILITY SERVICE Backend Application server Facility API Data and business logic CopilotKit Runtime AG-UI HttpAgent HTTP / JSON AG-UI /api/copilotkit AGENT SERVICE Google ADK default agent Instructions + model AG-UI MODEL LLM via llama.cpp Model API DATA STORAGE Database SQLite SQL query / rows /api/readings registerFrontendTool()
14
Soverius AI

AG-UI Demo

15
Soverius AI

Full-Stack Capstone Task

Angular

Angular

  • Feature component
  • UI component
  • SignalStore
  • Unit test
Spring

Spring

  • JPA entities
  • Mapper
  • Controller
  • Database migration
Playwright

Playwright

  • End-to-end test
16
Soverius AI

Benchmark Components

Security
NVIDIA OpenShell
Implementation
Pi coding agent
Inference engine
llama.cpp
Hardware
GX10
Tracing
Langfuse
Versioning
Git worktrees
17
Soverius AI

Benchmark Results

Spring Boot + Angular · Measured on ASUS GX10

ModelWeightsQuantizationTime (h:mm)Eff. Tokens/sValidationReview
Nemotron 3.5 Bolt 74B22.0 GBIQ22:3929.83/51/52 incomplete
Ternary Bonsai 2 27B5.9 GBPTQ1_04:0616.4*4/44/4
GLM-5.3 Flash97.6 GBIQ1_M1:2813.45/55/5
Muse Glimmer 30B15.9 GBQ4_K_XL3:0012.12/52/5
Qwen3.8 27B17.6 GBQ4_K_XL2:588.65/55/5
Gemma 4 26B-A4B QAT14.2 GBQ4_K_XL0:4652.52/41/41 incomplete
Gemma 4 31B QAT17.3 GBQ4_K_XL1:449.61/31/3
DeepSeek V4 Flash86.9 GBIQ1_M1:5915.03/43/4
Qwen3.6 27B17.6 GBQ4_K_XL3:059.35/55/5
Devstral Small 2 24B14.5 GBQ4_K_XL5:239.3*1/21/2
Qwen3-Coder 30B-A3B17.7 GBQ4_K_XL0:3436.90/50/5

47 runs · Medians · * Partial timing

18
Soverius AI

Tokens/s On Other Hardware

GX10 Measurement × Memory Bandwidth ÷ 273 GB/s

DeviceMemoryBandwidthEff. Tokens/s
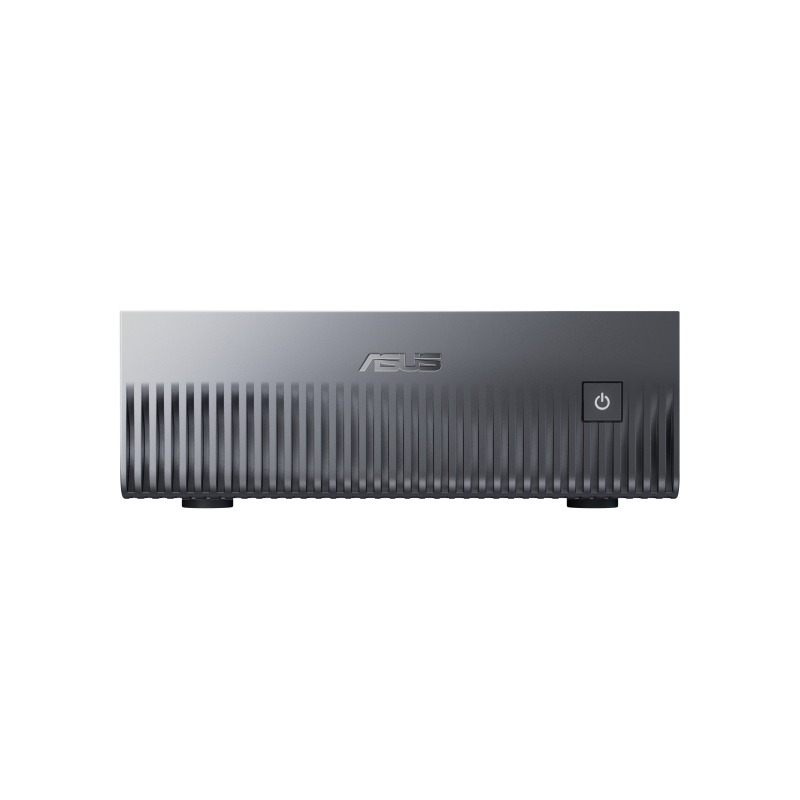
ASUS GX10 128 GB273 GB/s —
NVIDIA DGX Spark 128 GB273 GB/s —
MacBook Pro M5 Max 128 GB614 GB/s —
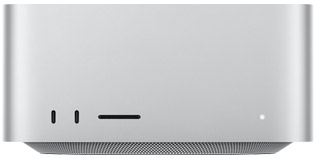
Mac Studio M5 Ultra 256 GB1,200 GB/s —
GeForce RTX 5090 32 GB1,792 GB/s —
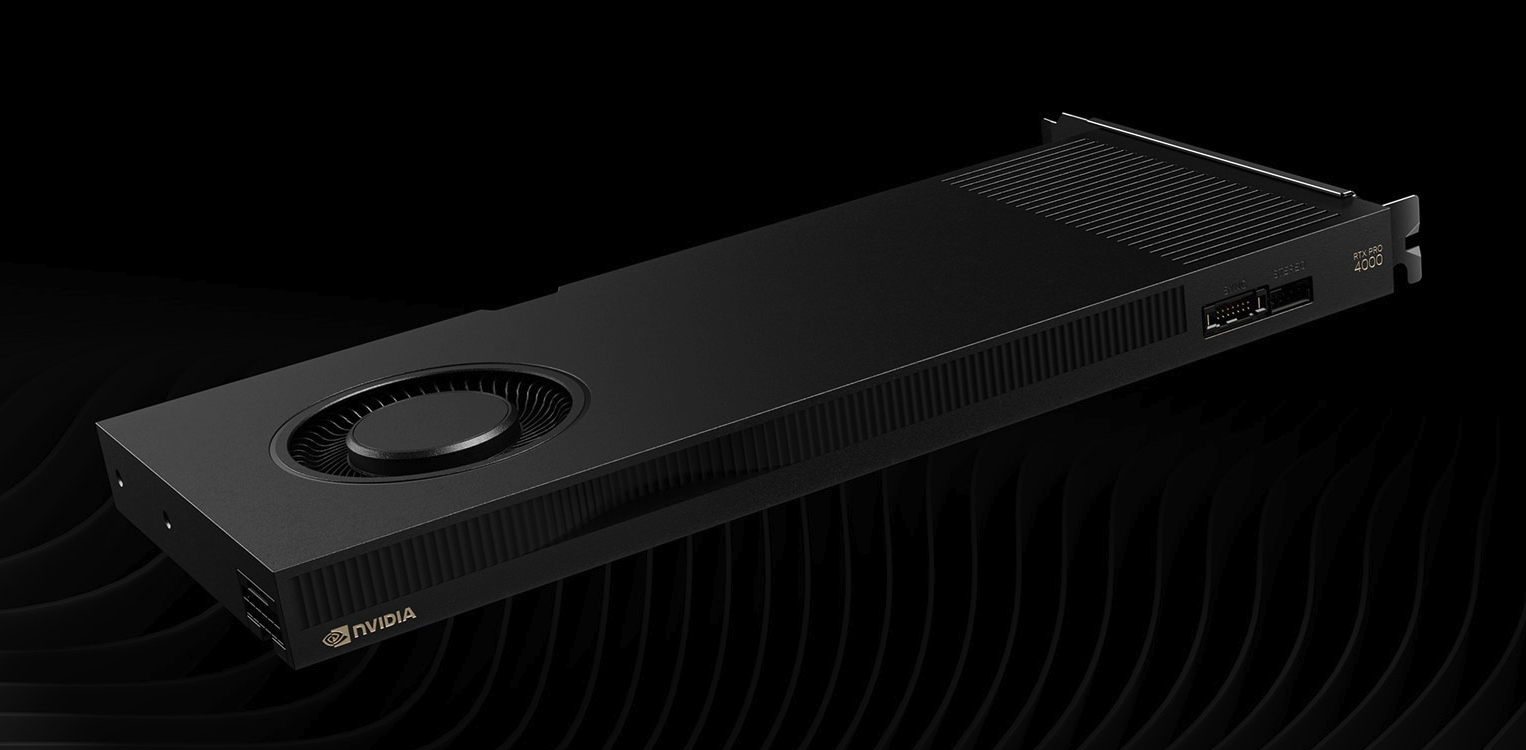
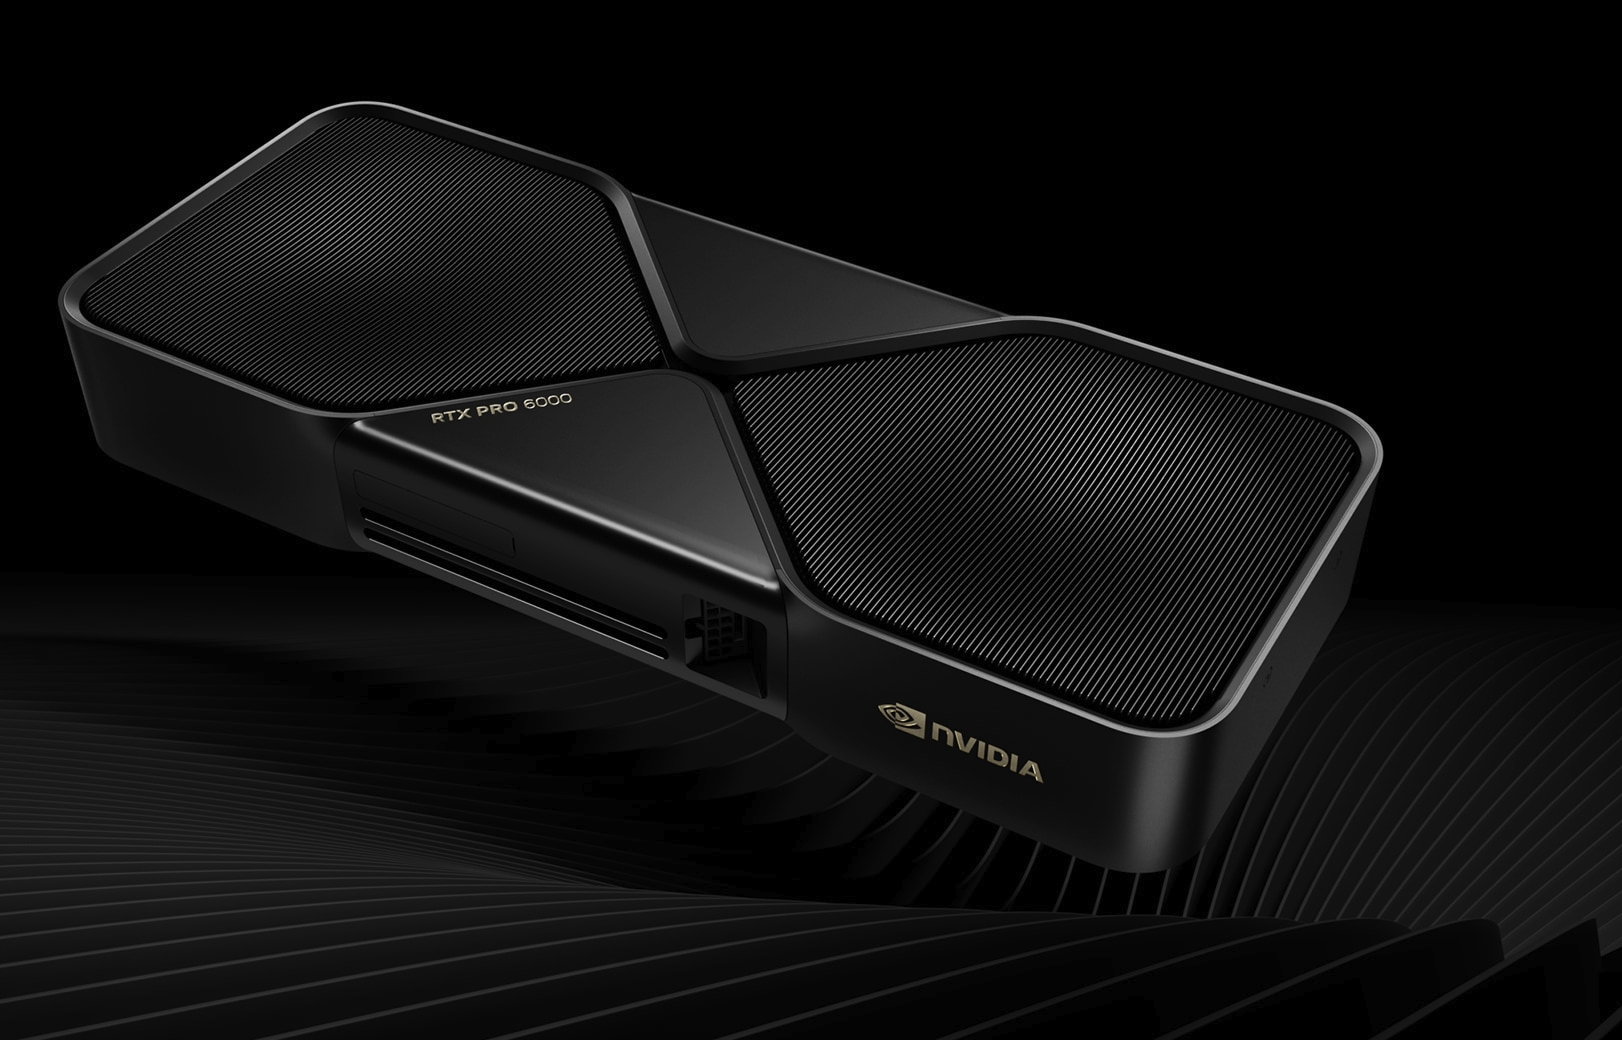
RTX PRO 6000 Blackwell 96 GB1,792 GB/s —

Blue = measured on GX10 · ≈ = bandwidth estimate

Estimates assume model weights, KV cache, and runtime buffers all fit in available GPU memory.

19
Soverius AI

Memory Provisioning (Gemma 4 26B)

Model

BF16

25.2B × 2 bytes
=50.4 GB

Quantization

K-Quant / UD-Q4_K_XL

50.4 GB ÷ 4 + overhead
≈14.25 GB

Ideal 4-bit: 12.6 GB

Context

128K / FP16 KV

131,072 tokens
+2.89 GB

Estimated KV cache

Total

Model + context

14.25 GB + 2.89 GB
≈17.14 GB

Before runtime overhead

20
Soverius AI

Local Inference Hardware

DE / AT Retail Examples · Incl. VAT · 19 November 2026
21

Presentation Controls

Next Step
Right arrow, Space, Page Down
Previous Step
Left arrow, Backspace, Page Up
Skip Slide
Shift + Right / Left arrow, or « / »
First / Last
Home / End
Overview
O
Toolbar
T - keep visible / auto-hide
Speaker Notes
N
Fullscreen
F
Close
Escape